
The Economics of Running AI Models on Private Infrastructure
As generative AI moves from pilots to production, one of the most consequential decisions for enterprises is where the models run. Public cloud providers promise speed and scalability; private infrastructure promises control and, potentially, lower long-run costs. The economics are far from straightforward, and they are changing quickly as hardware, software, and regulation evolve.
This article examines the financial and strategic trade-offs of running AI workloads on private infrastructure-whether in on-premises data centers, colocation facilities, or dedicated private clouds-versus relying primarily on public cloud services. The focus is on medium and large organizations building or heavily consuming AI models, rather than small teams experimenting with a few API calls.
Why companies are reconsidering where AI runs
Over the last decade, most new workloads migrated to public cloud, driven by elastic capacity, a rich ecosystem, and pay-as-you-go pricing. AI followed the same pattern, with training and inference workloads concentrated on AWS, Microsoft Azure, and Google Cloud. However, several factors are pushing enterprises to revisit private infrastructure economics:
First, AI workloads are unusually compute-intensive and, for many organizations, unusually predictable. Once a model is in production, inference volumes, latency requirements, and data flows often stabilize. That predictability makes it easier to sweat owned assets at high utilization-precisely where private infrastructure can undercut cloud on a per-unit basis. Second, GPU and specialized AI hardware pricing has shifted. While top-tier accelerators like NVIDIA's H100 remain expensive and supply-constrained, the emergence of more diverse options (such as AMD Instinct, Intel Gaudi, and various AI ASICs) gives large buyers more bargaining power and more incentive to build dedicated clusters. Third, data protection and compliance requirements are tightening. Regulators in Europe, North America, and parts of Asia are sharpening rules around data residency, model accountability, and AI safety. For heavily regulated sectors such as banking, healthcare, and government, keeping sensitive data and models on infrastructure they control can simplify compliance and reduce risk. Fourth, hyperscaler pricing and egress fees are under scrutiny. As organizations move from experimentation to sustained AI usage, line items for GPU instances, managed AI services, and data transfer can balloon, making multi-year private investments look more attractive.
This shift is not a simple "cloud versus on-prem" reversal. Instead, it is driving more nuanced hybrid strategies, where the most economically and strategically sensitive AI workloads run on private infrastructure, while burst capacity, experimentation, and some training still happen in public cloud. For business and technology leaders, the key question becomes: under what conditions does private infrastructure make economic sense?
Breaking down the cost structure of private AI infrastructure
To evaluate the economics, it is useful to separate the key cost components of running AI on private infrastructure: capital expenditure (CapEx), operational expenditure (OpEx), and organizational overhead. Each category carries distinct risks and levers.
CapEx starts with hardware. High-end GPUs and AI accelerators are the dominant cost driver in most AI clusters. A single data center-class GPU server can cost as much as a luxury car, and a full rack can easily run into the high six or seven figures, depending on configuration. Organizations must also account for CPUs, high-speed networking (such as InfiniBand or RoCE), storage systems tuned for AI workloads, and ancillary equipment. Beyond servers, there is the physical data center environment: racks, power distribution units, cooling systems, and potentially upgrades to power feeds or backup systems. Enterprises using colocation facilities must factor in long-term contracts and cross-connect fees. Software and licensing add another layer, including enterprise support for AI frameworks, orchestration platforms like Kubernetes, MLOps tooling, and sometimes commercial model licenses. While many AI frameworks are open source, enterprises often pay for hardened distributions or managed platforms.
OpEx includes energy, facilities, and ongoing operations. Power consumption is particularly significant: AI clusters are dense and energy-hungry, and electricity prices vary widely by region. Cooling costs are tightly coupled to power usage. Facilities costs include rent or colocation fees, maintenance contracts, and periodic upgrades. Operational staffing covers site reliability engineers, platform engineers, data center technicians, and MLOps teams required to keep the environment secure, performant, and compliant. Finally, organizational overhead includes procurement, vendor management, and governance processes that can slow deployment and add hidden costs. Many enterprises underestimate the time and coordination required to stand up and manage a high-performance AI environment, especially if they lack prior experience with GPU-dense workloads.
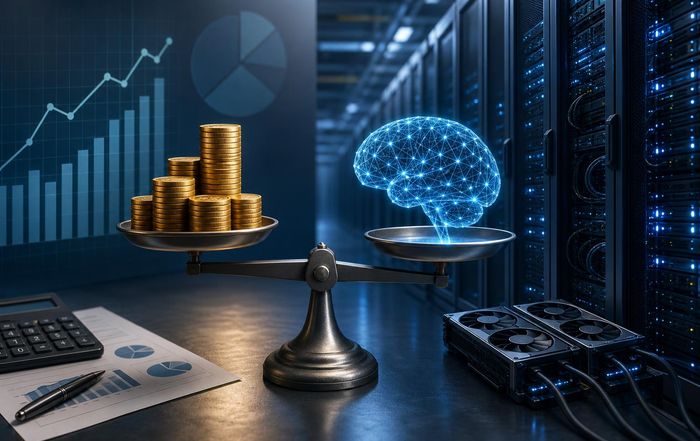
From a financial perspective, private infrastructure converts what would be variable operating costs in the cloud into fixed investments that must be amortized over several years. The economic viability hinges on utilization: the closer an organization can get to high sustained usage of its AI hardware, the more attractive private infrastructure becomes on a per-inference or per-training-run basis.
How public cloud pricing shapes the comparison
Understanding the economics of private infrastructure requires a realistic view of public cloud pricing for comparable AI workloads. Major clouds offer GPU instances, managed AI platforms, and fully hosted foundation model APIs. Each comes with distinct cost dynamics and lock-in characteristics.
GPU instances on AWS, Azure, and Google Cloud are typically priced by the hour, with higher rates for cutting-edge GPUs. Discounts are available via reserved instances, savings plans, or committed use discounts, which effectively trade flexibility for lower per-hour costs. However, these commitments start to resemble CapEx in economic terms: the organization is paying for capacity whether or not it is fully utilized. Managed AI services, such as Azure AI, Amazon Bedrock, and Google Vertex AI, bundle infrastructure with orchestration, MLOps, and integrations. They can reduce platform engineering overhead but often carry a premium over raw compute, especially when using proprietary services or tightly integrated offerings. Hosted model APIs, including OpenAI (via Azure), Anthropic, and others, shift costs to a per-token or per-call basis. This model is attractive for experimentation and for teams that do not want to manage infrastructure or models, but at scale, per-token pricing can exceed the cost of self-hosting open-weight models.
Data transfer and storage also influence the comparison. Egress fees-charges for moving data out of a cloud-can materially impact total cost of ownership for AI systems that integrate with on-premises systems or other clouds. While some providers have introduced more generous free tiers or caps in response to regulatory and competitive pressure, large AI workloads can still incur significant egress charges. Additionally, persistent storage of large training datasets and model checkpoints in object stores or block storage adds ongoing costs that may be cheaper on owned or colocated infrastructure, especially when storage requirements are relatively stable.
When organizations map these cloud costs over a three- to five-year horizon and compare them with the amortized cost of private infrastructure, they often find crossover points where owning hardware becomes cheaper-provided they can maintain high utilization and manage the operational complexity. This is particularly true for inference at scale, where workloads are steady and latency-sensitive.
When private AI infrastructure is likely to be cost-effective
Private infrastructure is not universally cheaper than cloud. Its advantages tend to emerge under specific conditions that align economic, technical, and regulatory factors. Understanding these conditions is critical for CIOs, CTOs, and CFOs considering large AI investments.
The first condition is sustained, high-volume workloads. Organizations that run large models continuously-such as recommendation systems, search, personalization engines, or internal copilots used by thousands of employees-can more easily keep GPU clusters busy. High utilization spreads fixed costs over more inferences or training steps, driving down unit economics. In contrast, sporadic or highly spiky workloads are better suited to elastic cloud capacity. The second condition is predictable demand and long planning horizons. If an organization can reasonably forecast its AI usage over several years, it can size infrastructure accordingly and avoid both overprovisioning and chronic shortages. This predictability is more common in established enterprises than in early-stage startups, which often face volatile demand and evolving business models.
A third condition is strong data-sovereignty or security requirements. Highly regulated sectors such as banking and healthcare, or governments operating under strict sovereignty laws, may find that keeping data and models on infrastructure they control reduces compliance burden and legal risk. In these cases, some of the "extra" cost of private infrastructure can be justified as risk mitigation. For readers following developments in global regulation, resources from organizations such as the European Commission at https://europa.eu/ and the U.S. Federal Trade Commission at https://www.ftc.gov/ provide useful context on emerging AI rules.
A fourth condition is organizational scale and capability. Large technology companies, hyperscalers, and AI-first firms have long argued that owning infrastructure is cheaper at scale, a view echoed in analyses by cloud-native firms and infrastructure providers. Enterprises with mature data center operations, strong platform engineering teams, and existing colocation footprints are better positioned to capture these economies than organizations starting from scratch. Finally, access to favorable energy and real estate markets can tilt the balance. Regions with low electricity prices, stable grids, and competitive colocation markets make private AI infrastructure more attractive. In contrast, enterprises in high-cost or capacity-constrained markets may find that cloud providers, with their global scale and energy procurement strategies, maintain an edge.
For businesses that meet several of these conditions, private AI infrastructure can be economically compelling, especially for large-scale inference and for training specialized models. However, even in these cases, most organizations pair private capacity with public cloud to handle bursts, experiments, and workloads that do not justify dedicated hardware.
Strategic benefits beyond pure cost
While cost is central, the economics of private AI infrastructure are also shaped by strategic considerations that may not show up directly in a spreadsheet but still have financial implications over time.
One important factor is bargaining power and vendor diversification. Organizations that own substantial AI infrastructure have more leverage when negotiating with cloud providers and AI vendors. They can credibly shift workloads between environments and avoid being locked into a single provider's pricing, roadmap, or technology stack. This diversification can be especially important for enterprises using multiple AI models, including open-weight models hosted on their own infrastructure and proprietary models accessed via APIs. Another factor is control over performance and latency. For latency-sensitive applications-such as real-time trading, industrial control systems, or consumer services requiring sub-second responses-placing AI infrastructure physically close to users or critical systems can improve user experience and reduce reliance on long-haul network links. Organizations with global footprints may choose a mix of private and public infrastructure across regions to balance performance, cost, and compliance.
Intellectual property and model governance also play roles. Training or fine-tuning models on proprietary data in a private environment can reduce the risk of inadvertent data leakage and provide clearer lines of accountability. Internal legal and risk teams may prefer environments where logging, access control, and audit trails are fully under the organization's control, especially as AI regulations evolve. Resources such as the OECD's AI principles at https://www.oecd.org/ and the OECD AI Policy Observatory can help contextualize these governance concerns.
Talent and innovation dynamics are another dimension. Building and operating private AI infrastructure can attract and retain specialized engineering talent interested in working close to the metal. For some organizations, this capability becomes a strategic asset, enabling more aggressive experimentation with custom models, architectures, or optimization techniques that might be constrained by managed cloud services. However, it can also create organizational complexity if not aligned with clear business objectives.
These strategic benefits do not eliminate the need for rigorous financial analysis, but they can justify private infrastructure in scenarios where a narrow cost comparison might look marginal. For business leaders, the challenge is to quantify, as much as possible, the value of control, resilience, and strategic flexibility.
Key economic risks and hidden costs of private AI
Despite its potential advantages, private AI infrastructure carries material risks that can erode or even reverse the expected economic benefits if not managed carefully.
The most obvious risk is underutilization. If AI hardware sits idle for large portions of the day, the effective cost per inference or training step rises sharply. Many organizations overestimate the volume and steadiness of their AI workloads, especially in the early stages of adoption. Without careful capacity planning and workload consolidation, it is easy to end up with expensive clusters that are busy only during peak hours or specific projects. A related risk is technological obsolescence. AI hardware cycles are moving quickly, with new GPU generations, accelerators, and interconnects arriving rapidly. Committing large capital budgets to hardware that may be outclassed within two or three years introduces depreciation and opportunity-cost risks. Cloud providers absorb much of this risk for their customers; private infrastructure owners bear it directly.
Operational complexity is another significant hidden cost. Running high-performance AI clusters requires expertise in areas such as GPU scheduling, container orchestration, networking, storage optimization, and security. Organizations that underestimate these demands may experience outages, performance degradation, or security incidents that carry both direct costs and reputational damage. Industry bodies such as the Uptime Institute at https://uptimeinstitute.com/ and technical communities around Linux Foundation projects at https://www.linuxfoundation.org/ provide guidance on best practices, but implementing them at scale is non-trivial.
Regulatory and compliance drift also matter. Laws governing AI, data protection, and cybersecurity are evolving quickly. Infrastructure that is compliant today may require costly upgrades or reconfiguration tomorrow to meet new standards. For global enterprises, ensuring that private AI facilities in different jurisdictions meet local requirements can become complex and expensive. Additionally, opportunity costs deserve attention. Capital tied up in data centers and AI hardware is capital not available for other strategic investments, such as acquisitions, product development, or market expansion. CFOs must weigh the potential savings from private infrastructure against alternative uses of funds, particularly in uncertain macroeconomic environments.
Finally, there is the risk of organizational misalignment. Building private AI infrastructure without a clear, agreed-upon strategy for how it supports products, services, or internal productivity can lead to "AI islands" that are technically impressive but underused or disconnected from business outcomes. Governance structures that tie infrastructure investments to concrete business objectives are crucial to avoid this trap.
How model choice and architecture affect infrastructure economics
The economics of private AI infrastructure are tightly coupled to the models an organization chooses and how they are deployed. Different model sizes, architectures, and usage patterns can produce radically different cost profiles, even on the same hardware.
Large foundation models with hundreds of billions of parameters demand substantial GPU memory, high-bandwidth interconnects, and careful distributed inference or training strategies. Running such models privately can require clusters that only the largest enterprises or governments can justify. However, the growing ecosystem of open-weight models-maintained by organizations such as Meta (with Llama), Mistral AI, and various research labs-has expanded the range of options. Many of these models can be fine-tuned and deployed efficiently on smaller clusters, especially when combined with techniques such as quantization and distillation. For readers tracking model developments, communities like Hugging Face at https://huggingface.co/ and research hubs such as arXiv at https://arxiv.org/ offer insight into emerging architectures and benchmarks.
Smaller, specialized models often deliver better economics on private infrastructure than monolithic general-purpose models. A company might deploy multiple task-specific models-one for document summarization, another for classification, another for code assistance-each optimized for its workload and hardware. This modular approach can improve utilization by matching model requirements to available resources, instead of forcing every task through a single large model. Techniques like retrieval-augmented generation (RAG) further shift the balance. By pairing moderately sized language models with high-quality vector search over proprietary data, organizations can achieve strong performance for many enterprise use cases without the cost of running the very largest models. This can lower both inference costs and data-movement overhead, particularly when the search index and models are co-located on the same private infrastructure.
Deployment architecture also shapes economics. For example, centralizing AI workloads in a few large data centers can simplify management and maximize hardware utilization but may introduce latency for distant users. Distributed or edge deployments, where smaller models run closer to users or devices, can improve responsiveness and reduce backbone network costs but may result in lower utilization of each node. Organizations must weigh these trade-offs in light of their specific applications, user geography, and tolerance for latency. Internal platform teams that manage AI as a shared service across business units can help consolidate demand and smooth utilization, making private infrastructure more economical.
Hybrid and multi-cloud strategies: blending economics and flexibility
For most enterprises, the economically rational path is not a binary choice between public cloud and private infrastructure but a hybrid or multi-cloud strategy that leverages the strengths of each environment. Executed well, such strategies can balance cost, flexibility, and resilience.
A common pattern is to run steady, high-volume inference workloads on private infrastructure while using public cloud for burst capacity, experimentation, and large-scale training. For example, an organization might host its core customer-facing AI services on its own GPU clusters to ensure predictable costs and performance, while spinning up cloud resources to train new models or run large one-off experiments. When demand spikes-such as during product launches or seasonal peaks-cloud capacity can absorb the load without requiring permanent overprovisioning of private hardware. Another pattern is multi-cloud plus private, where organizations use multiple public clouds alongside their own infrastructure to avoid concentration risk and take advantage of specialized services. This approach can improve bargaining power and resilience but adds complexity in networking, security, and data governance. Tools and standards from organizations like the Cloud Native Computing Foundation at https://www.cncf.io/ and open-source projects in the Kubernetes ecosystem aim to ease some of this complexity.
Hybrid strategies also influence data-management economics. Frequently accessed, sensitive datasets might reside on private infrastructure, with derived or anonymized data replicated to the cloud for model training or analytics. This can reduce egress costs and simplify compliance while still benefiting from the cloud's scale for certain workloads. For readers interested in broader economic and policy implications of such infrastructure decisions, institutions like the International Monetary Fund at https://www.imf.org/ and World Bank at https://www.worldbank.org/ periodically publish analyses on digital infrastructure and productivity that provide useful macro-level context.
The success of hybrid and multi-cloud models depends heavily on internal capabilities. Platform engineering, network architecture, identity and access management, and observability must be robust enough to span multiple environments without creating security gaps or operational blind spots. Done poorly, hybrid strategies can introduce enough complexity to negate their theoretical economic benefits.
Practical steps for evaluating your AI infrastructure economics
For executives and technology leaders weighing private AI investments, a structured evaluation can clarify when and how such moves make sense. While every organization's situation is unique, several practical steps can improve decision quality.
First, quantify workloads in as much detail as possible. This includes current and projected inference volumes, latency requirements, model sizes, training schedules, and data-movement patterns. Many organizations find it useful to categorize workloads into tiers-mission-critical, important but flexible, and experimental-to match them with appropriate infrastructure. Second, model total cost of ownership over realistic time horizons, typically three to five years. This should include hardware, facilities, energy, staffing, software licensing, and depreciation, as well as cloud costs for comparable workloads. Sensitivity analyses-varying assumptions about utilization, energy prices, and hardware refresh cycles-can reveal how robust the economics are to uncertainty.
Third, incorporate regulatory and risk considerations explicitly. For sectors like banking, where regulatory expectations are evolving quickly, engaging with regulators early and understanding guidance from bodies such as the Bank for International Settlements at https://www.bis.org/ can help avoid costly surprises. Internal risk committees should assess data-sovereignty, cybersecurity, and AI-governance implications alongside financial metrics. Fourth, assess organizational readiness. This includes evaluating data center operations, platform engineering, MLOps maturity, procurement processes, and talent availability. In some cases, partnering with specialized colocation providers or managed service firms can bridge gaps, but these arrangements must be reflected in TCO models.
Finally, start with targeted pilots rather than wholesale shifts. For example, an enterprise might move a single, high-volume inference workload to a small private cluster and compare real-world economics and performance with cloud baselines. Lessons from such pilots can inform broader rollouts and help refine assumptions. Throughout, it is useful to benchmark against peers and industry trends. Business-focused outlets, including https://www.biznewsfeed.com/business.html, https://www.biznewsfeed.com/technology.html, and https://www.biznewsfeed.com/ai.html, as well as major technology and financial publications like The Financial Times at https://www.ft.com/ and The Wall Street Journal at https://www.wsj.com/, regularly report on how leading firms are structuring their AI infrastructure investments.
Where the economics are heading
The economics of running AI models on private infrastructure are not static. Hardware roadmaps, cloud-provider strategies, regulatory developments, and the evolution of AI models themselves will all influence the balance over the next several years.
On the hardware side, more diverse accelerators and competition among GPU vendors are likely to put downward pressure on prices and expand the set of viable configurations for private clusters. Advances in model efficiency-through better architectures, compression, and new training techniques-may reduce the need for the largest, most power-hungry systems in many enterprise scenarios. At the same time, cloud providers are investing heavily in custom silicon and vertically integrated AI stacks, aiming to offer performance and cost profiles that are difficult to match privately. Their ability to spread R&D and capital costs across vast customer bases will remain a formidable advantage, particularly for organizations without the scale or appetite to manage their own AI infrastructure.
Regulation and public policy will also shape the landscape. Moves by governments to encourage domestic data centers, promote energy-efficient computing, or regulate cross-border data flows could tilt the economics toward or away from private infrastructure in specific regions. Sustainability considerations-such as carbon pricing, renewable-energy mandates, and reporting requirements-may further complicate cost models. Organizations tracking these trends can benefit from resources provided by bodies like the International Energy Agency at https://www.iea.org/ and sustainability-focused sections such as https://www.biznewsfeed.com/sustainable.html.
For now, the most robust conclusion is that neither private infrastructure nor public cloud will dominate all AI workloads. Instead, enterprises are likely to converge on nuanced, workload-aware strategies that blend private clusters, multiple clouds, and specialized AI services. The winners will be organizations that treat AI infrastructure as a portfolio of economic and strategic bets, grounded in clear business objectives, disciplined financial analysis, and an honest assessment of their own capabilities.
For leaders navigating this transition, staying informed about broader economy and markets developments via resources like https://www.biznewsfeed.com/economy.html and https://www.biznewsfeed.com/markets.html, as well as tracking global news at https://www.biznewsfeed.com/news.html and https://www.biznewsfeed.com/global.html, can provide the macro context needed to make resilient, long-term AI infrastructure decisions.